
Critical alerts Monitoring system. Automated on-call cascade
4.8(6)12SaaSAPIDevelopment Tools
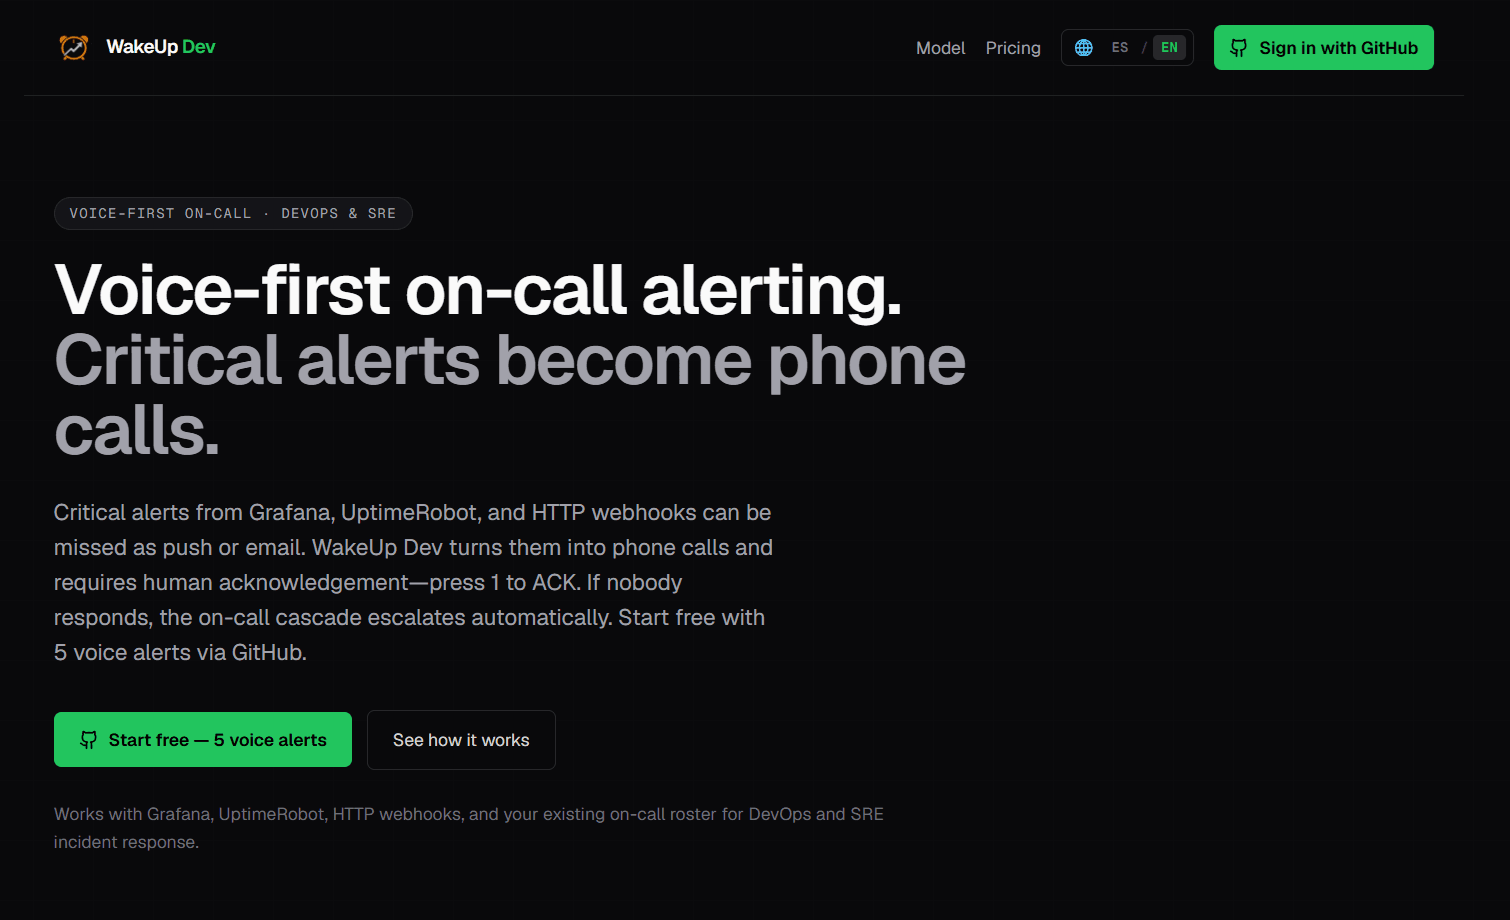
WakeUp Dev changes how dev teams handle incident response. Instead of drowning in ignored emails or missed push notifications, critical alerts from Grafana and UptimeRobot are instantly turned into automated phone calls. Responders can easily acknowledge by pressing 1, or the platform triggers an automatic on-call cascade. Built for modern DevOps and SRE teams with an honest pay-per-alert pricing model. No forced per-seat subscriptions.
4.8
6 ratings

AI video with native sound, paid per clip. Nothing stored.

A calmer Mac menu bar, one click away.

Enterprise Software. Intelligent Automation. Global Impact.


Comments
12Hi Fazier community! I’m Enrique, the creator of WakeUp Dev. As a developer, I’ve been on-call many times and experienced the anxiety of missing a critical server alert just because it was buried under a pile of Slack notifications or promotional emails during the night. Standard push notifications simply don't wake you up when production goes down. That’s why I built WakeUp Dev. I wanted a bulletproof system that transforms standard HTTP webhooks (from Grafana, UptimeRobot, or any monitoring tool) into immediate, loud phone calls. To make it developer-friendly and fair, I focused on two core pillars: 1. Eliminating voicemail false-positives by requiring an interactive touch-tone response (Press 1 to ACK). If there is no answer, it automatically triggers an on-call cascade to the next engineer. 2. Fair pricing: No forced monthly subscriptions per user seat. You only pay for the actual volume of alerts dispatched, making it perfect for growing teams and side projects.
We are offering an exclusive 20% off our Pro International Plan for the Fazier community using the coupon code PRODUCTHUNT20 (Valid until October 29, 2026).
🤖 For technical teams and custom monitors, we've just open-sourced our official Integration Toolbox. You can grab copy-paste scripts for Python, Node.js, and Bash/cURL directly from our GitHub: https://github.com/enriquecasadesign1957/wakeup-dev-integrations
Press 1 to acknowledge is the right call; a voicemail pickup should never count as someone being awake. Two questions from running on-call before: how do you handle an alert storm, when Grafana fires twenty webhooks for one outage? With pay-per-alert pricing, grouping or deduplication by alert name would matter a lot. And is there a fallback to SMS when a call cannot connect, for responders travelling abroad?
On-call and monitoring is one of those areas where the gap between enterprise tools and indie-friendly pricing is enormous. The automated escalation is the right call — the problem with manual on-call is that a missed notification at 3am can cascade into a much bigger issue by morning.
I am a software enthusiast.
The CSV roster's atomic replace raises an on-call handover question: if the roster changes while an escalation is already running, does that incident keep the original contact sequence or use the new one? Keeping the roster version in the incident history would make missed handovers easier to investigate.
Bringing founders early users and feedback to help them refine their software products.
Curious whether Wakeup Dev makes on-call cascades and critical alerts feel trustworthy before a team wires production monitors. Can send a totally free first-impression video if helpful.
Transforming monitoring alerts into reliable automated phone escalations solves a major alert fatigue problem with Slack and email noise. Automated cascading escalation is especially vital for lean engineering teams maintaining 24/7 reliability.
Voice acknowledgement plus an automatic cascade is a thoughtful approach. Have you considered scheduled test calls and reporting time-to-acknowledge? Teams need a simple way to prove the entire escalation chain still works after roster or timezone changes, before a real outage happens.
Building features to make hiring great again
Pay-per-alert pricing is a real differentiator for small teams, where per-seat on-call tools cost more than the incidents they catch. One question on the cascade: when it reaches the last engineer and nobody presses 1, does it loop back to the first responder, or stop and post a summary somewhere, like Slack or email, so the morning shift sees what went unanswered?
Requiring a human to press 1 avoids the voicemail acknowledgement problem. How are retries from Grafana or UptimeRobot handled when an incident is already acknowledged? An idempotency key and a visible incident timeline would help teams avoid duplicate calls and understand exactly when escalation stopped.
Super useful to check my website health on render and other backend sites.