
Tokonomics is an API proxy that sits between your app and any LLM provider (OpenAI, Anthropic, DeepSeek, Google Gemini, xAI, Mistral). It tracks every token, calculates cost per call, and enforces budget limits in real time. One line change in your code — works with any language and any HTTP client. Free tier available, Pro at $49/mo.
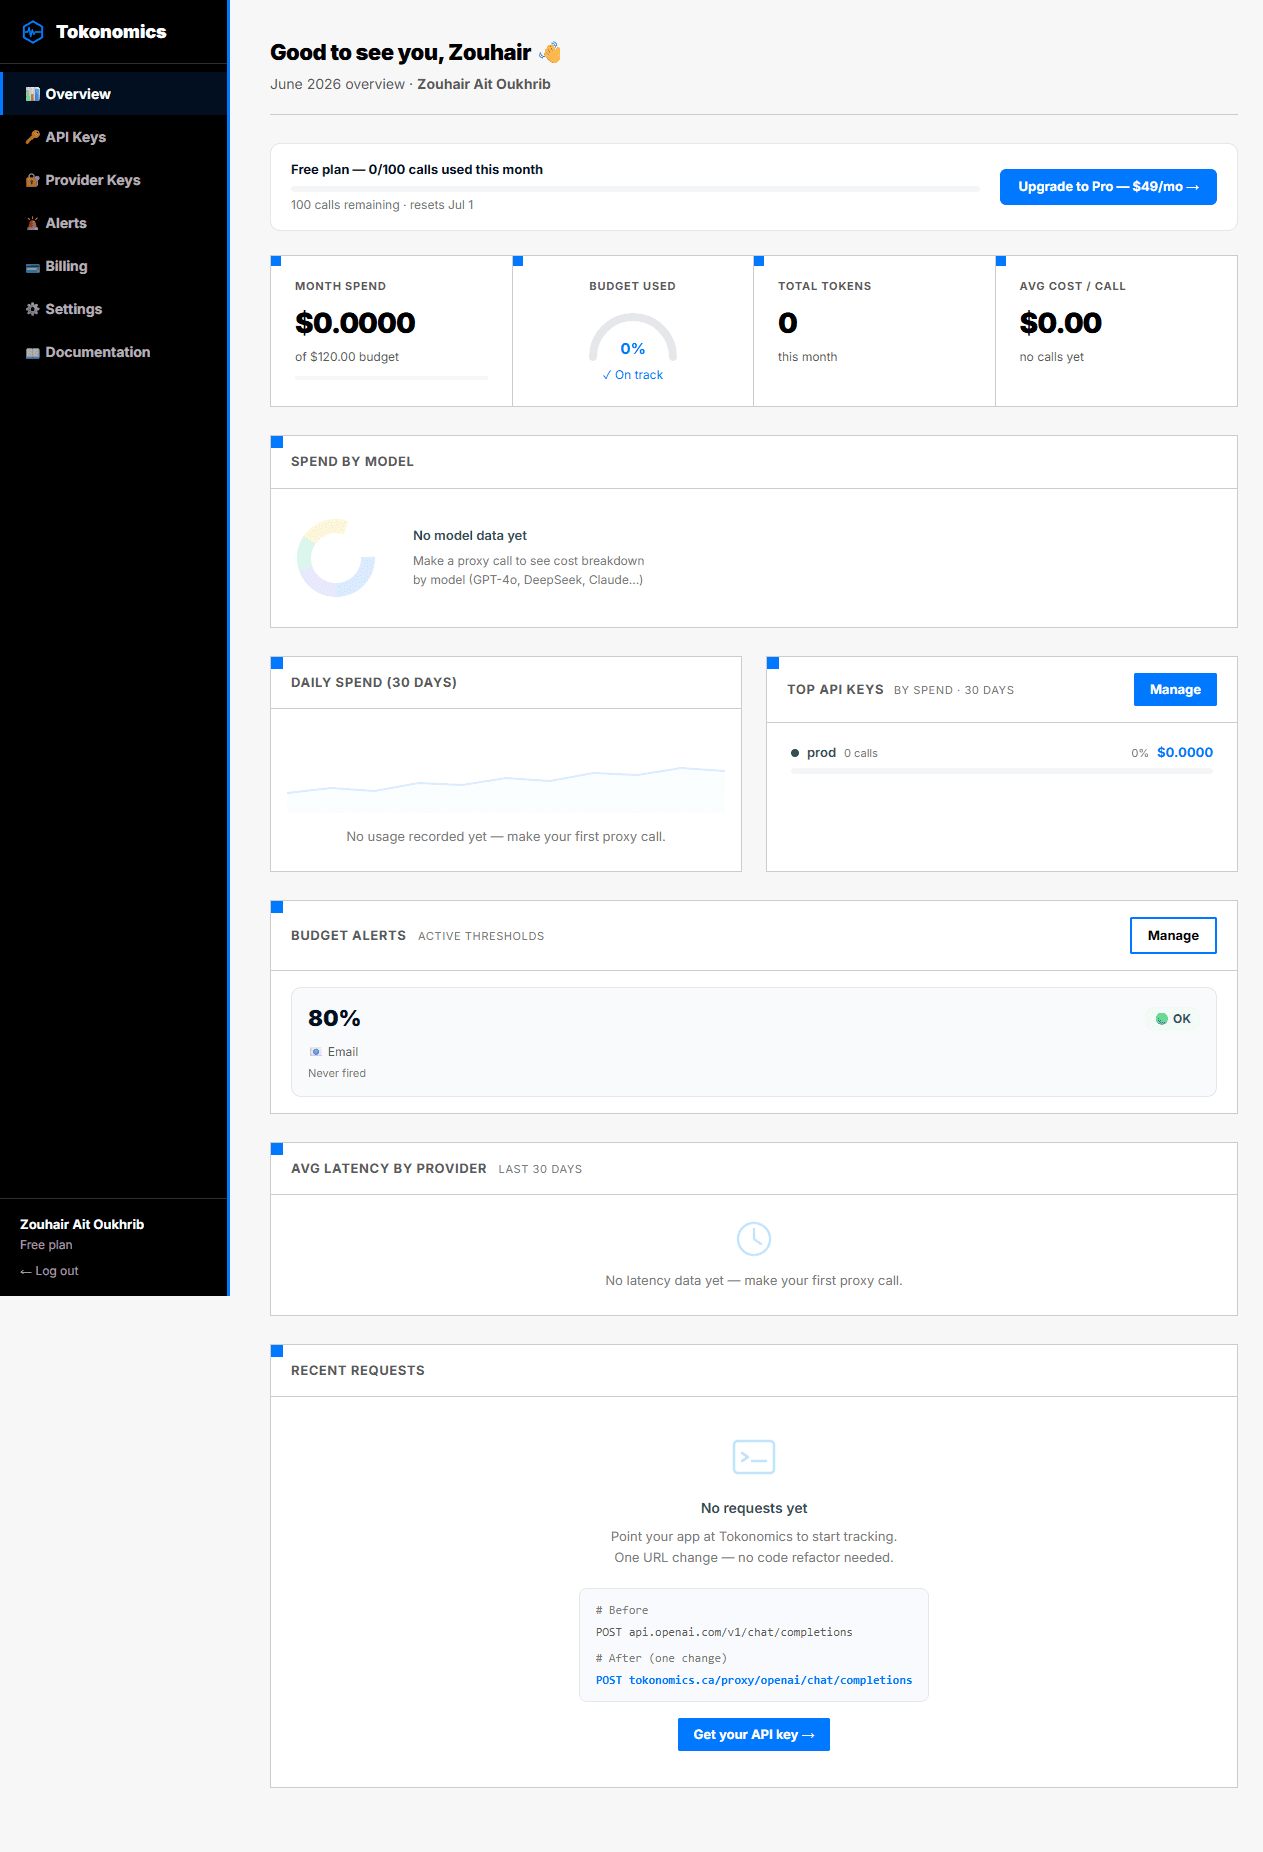
• Real-time token tracking across all LLM providers
• Hard spending caps via Redis (sub-1ms budget checks)
• Budget alerts via email, Slack, and Microsoft Teams
• Per-feature and per-team cost breakdowns with custom tags
• AI cost optimization reports with model downgrade suggestions
• Rate limiting per API key (sliding window)
• Prompt cache savings tracking (OpenAI, Anthropic, DeepSeek, Gemini)
• 6 free developer tools (token counter, cost calculator, prompt optimizer, API builder, model matrix, ROI calculator)
• SaaS founders tracking AI costs per feature before they spiral
• Agencies isolating LLM spend per client with hard budget caps
• Startup CTOs generating monthly cost reports for board meetings
• ML engineers preventing runaway batch jobs with real-time alerts
• No-code builders (n8n, Make, Zapier) monitoring per-workflow AI costs
• Finance teams auditing AI spend across departments and teams
68 people supporting this launch
4.8
6 ratings


AI video with native sound, paid per clip. Nothing stored.

A calmer Mac menu bar, one click away.

Enterprise Software. Intelligent Automation. Global Impact.


Comments
14I built Tokonomics after receiving a $47,000 LLM invoice that nobody on my team saw coming. We had no visibility into which features were burning tokens, which models were overkill, or when spending crossed our budget. Existing tools were either observability-first (great for debugging, not for budgeting) or required you to rewrite your code with a specific SDK. Tokonomics is a proxy — one line change, any language, any provider. It tracks every token, enforces hard spending caps in real time, and sends alerts before you blow your budget. Free tier available, happy to hear your feedback!
i write a16z speedrun scout checks within 24hours | Co-Founder & CTO at Dial AI
The real problem this solves is visibility into AI costs before they spiral. Most teams using multiple LLM providers have no idea which models are actually expensive until the bill arrives. Being able to set hard budget caps and see cost per call across OpenAI, Anthropic, and others in one dashboard is huge. The model downgrade suggestions piece is clever too - you can actually optimize without rewriting code. Sub-millisecond budget checks via Redis is also key for high-throughput apps where latency matters.
AI that takes webinar attendance from 30% to 62%
This is exactly what I needed when building ShowUp.ai — Claude API costs were completely unpredictable until I started tracking manually. One line change is a genuinely low friction way to get this in. Does the budget enforcement hard stop the calls or just alert when limit is hit?
AI cost tracking is becoming essential as teams adopt multiple LLM providers. The one-line-change approach makes this practical to adopt — no one wants to refactor their codebase just to add budget monitoring. Real-time budget enforcement is the killer feature here: getting a surprise invoice is a real fear for teams scaling AI usage. The proxy architecture is smart because it works with any stack without SDK lock-in.
The one-line-change integration plus hard spending caps via Redis is a clean way to stop runaway LLM bills. Does the budget cap actually block requests at the proxy or just fire alerts?
Rating Captain - AI-powered reputation and local SEO management for Google Business Profile. Monitor reviews, automate replies, and grow your local visibility.
Looks nice, will definietly try it ou
Founder at Unfurl — share links that actually look good.
Love the approach of tracking AI costs at the model level. The budget-first framing is genuinely useful for teams that need predictable spend without sacrificing model choice. Curious how it handles multi-modal requests — does cost metering extend to image/audio tokens too?
Ship more
Love the approach of tracking AI costs at the model level.
Founder of ELVITA STUDIO, building AI tools, Telegram bots and web products for everyday business tasks.
Выглядит неплохо, обязательно попробую.
Cofounder of Autosprite
This honestly would be so helpful for our budget control. Excited to see more features
Founder of freephotobooth.online
This solves a very real problem. LLM costs can get messy fast, especially when a product uses multiple providers. I like the proxy approach because teams don’t need to rewrite everything around a new SDK just to see where the money is going.
The $47k-invoice origin story is exactly why this clicks — every team on multiple providers is one runaway batch job away from that, and a proxy you drop in with one line is the least painful way to see it coming. Hard budget caps over just alerts is the right call. One launch-day thing: a short demo tends to pull more people in than a description alone, and you shipped without one — so I made you one, free, branded only to you, no strings: https://foxplug.com/v/ss-tokonomics-stop-surprise-ai--bc1fd886 Suggest getting the the video from that page, download, upload to Youtube so it's your's and then add to your launch in here. Use in PH too, if you've not done that site yet, too! Use it on your launch, your site, wherever. I made it at https://foxplug.com/?utm_source=fazier&utm_medium=comment — you can make more there, or record your own real product tour in about two minutes. Anyone else launching soon: paste your site and you'll have a video in ~30 seconds. Nice work, Zouhair.
Budget management is becoming one of the biggest challenges when working with multiple LLMs, so having real-time token tracking alongside spending limits is a practical feature. I especially like the ability to set hard budgets and receive alerts before costs get out of control. It would be interesting to see team-level reporting and historical usage trends as well.
Founder at Plantory
The per-feature cost breakdown with custom tags is the part most teams actually miss — we track AI spend per feature in our product and had to build that attribution ourselves. Proxy with sub-ms Redis budget checks is a pragmatic design. One question: how do you handle streaming responses when a hard cap is hit mid-stream — cut the stream or let it finish and flag it?