
Prove your PostgreSQL backups actually work
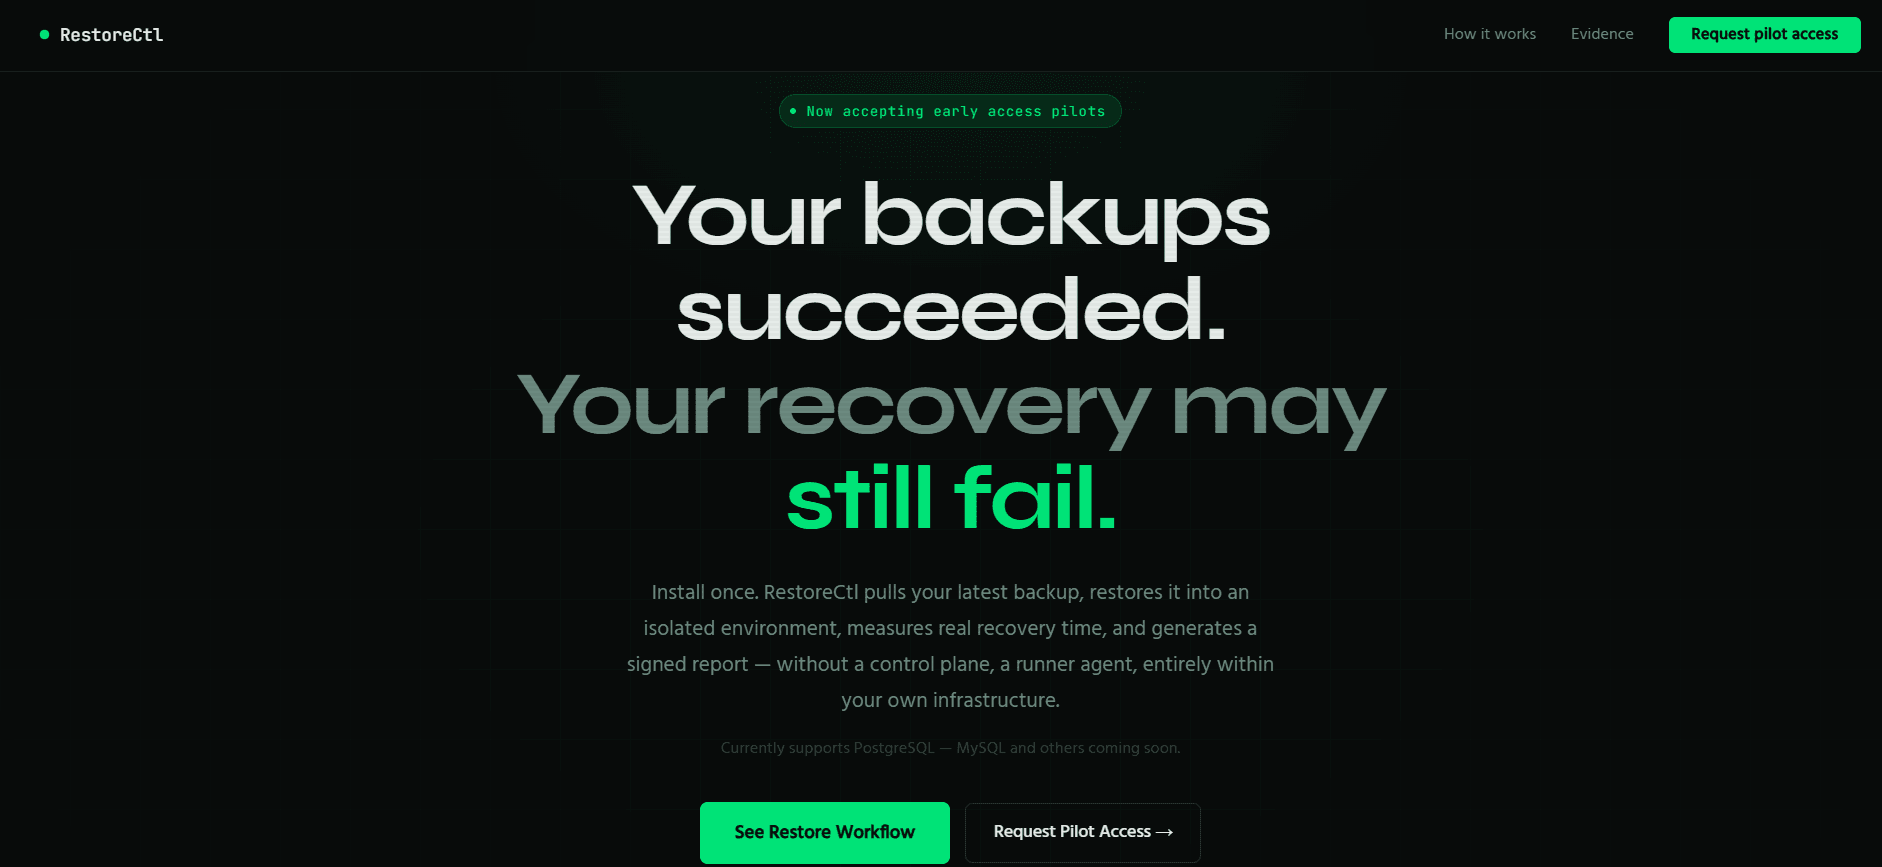
RestoreCtl automatically tests PostgreSQL backups by running real restore drills inside isolated environments.
It verifies backup integrity, measures actual recovery time (RTO), and generates audit-ready recovery reports, entirely within your own infrastructure.
No agents. No control plane. No cloud dashboard.
Compatible with existing PostgreSQL backup workflows, including pg_dump, pgBackRest, WAL-G, and custom backup pipelines.
Validate PostgreSQL backups automatically
Disaster recovery readiness testing
SOC 2 and ISO 27001 restore evidence
Detect corrupted or incomplete backups
Verify backup integrity before incidents happen
Measure real-world restore performance
Continuous backup recovery verification for production systems
6 ratings

DevOps Engineer

AI video with native sound, paid per clip. Nothing stored.

A calmer Mac menu bar, one click away.

Enterprise Software. Intelligent Automation. Global Impact.


Comments
7DevOps Engineer
RestoreCtl started after noticing a recurring problem in production systems: backups were “successful,” but nobody had actually verified whether recovery would work during a real incident. Most teams monitor backup creation. Very few continuously test restore integrity, recovery time, or whether data can actually be recovered correctly. RestoreCtl was built to automate restore drills for PostgreSQL backups inside isolated environments, validate integrity, measure real recovery time, and generate audit-ready reports, without requiring agents or a hosted control plane. Currently focused on PostgreSQL pilots and actively looking for feedback from DevOps, SRE, and platform engineering teams.
The 'ephemeral isolated restore + real RTO measurement + cryptographic integrity check' combo is the right approach. Most teams treat a successful pg_dump as 'backup done' and never measure actual restore time until an incident forces them to. Audit-ready PDF/JSON for SOC 2 evidence is a smart touch too. Does the measured RTO scale with data volume, so you can see how recovery time grows as the DB gets bigger?
DevOps Engineer
RTO really depends on the database itself, size, indexes, hardware, all of it. RestoreCtl isn't predicting it, just measuring the real number on your own setup so you're not flying blind. Haven't tested it across huge DBs yet, but my guess is it won't be linear. Would love to know if you have seen any such patterns.
Strong positioning: testing the restore path is where most backup plans fail. A trend view for RTO over time and backup size would be especially useful for SRE teams, with alert thresholds when drill duration or verification failures regress. That would make the reports useful for capacity planning as well as audits.
DevOps Engineer
That's a great point, alert thresholds on drill regression would make this way more useful day to day instead of just at audit time. Adding that to the list, thanks.
Restore drill automation is the part of backup strategy most solo teams skip until it's too late. "We have backups" and "we've verified the restore works and measured how long it takes" are very different claims, this closes that gap nicely.
DevOps Engineer
Appreciate it, that gap was the whole reason I started building this.