
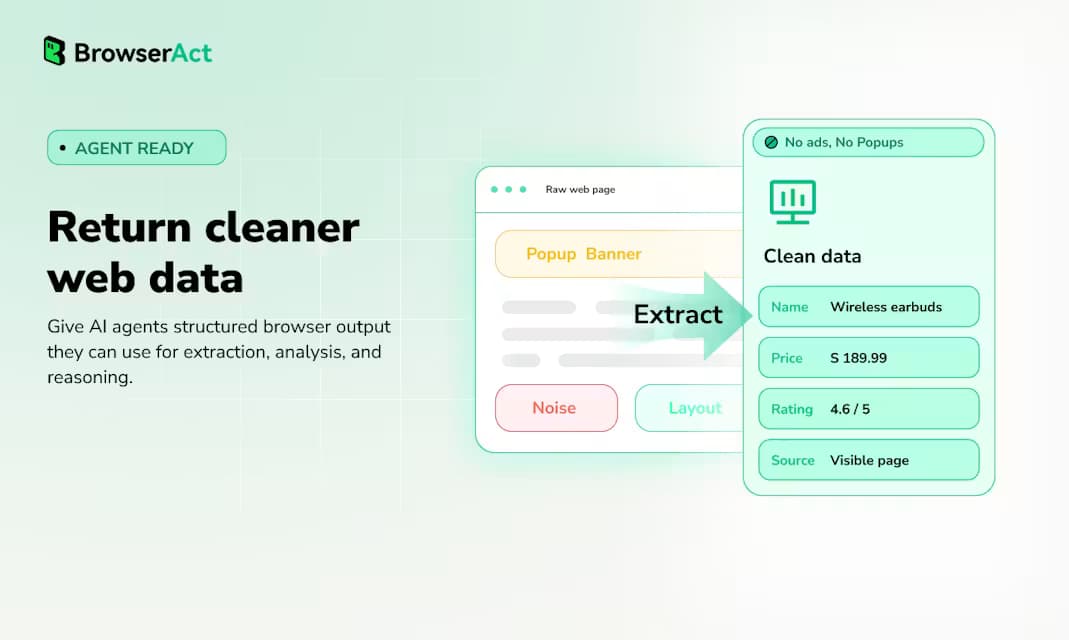
BrowserAct is built for agents using the web. It gives agents a browser layer for real websites, so they can pass blocked pages, adapt to real scenarios, run multiple tasks safely, and return clean web data for reasoning. Use BrowserAct when an agent needs to browse, click, extract, fill forms, upload files, work inside logged-in sites, handle verification, or run repeatable browser workflows.
Features
Use BrowserAct Skills when your AI agent needs to operate real websites instead of clean APIs. It helps agents scrape protected pages, work inside logged-in dashboards, collect competitor or market data, automate multi-step web tasks, manage parallel browser sessions, and recover from CAPTCHAs, 2FA, bot checks, or UI changes with remote human handoff. It is especially useful for AI coding agents, data extraction, browser automation, research workflows, QA, and repeatable operations across real websites.
68 people supporting this launch
4.8
6 ratings


AI video with native sound, paid per clip. Nothing stored.

A calmer Mac menu bar, one click away.

Enterprise Software. Intelligent Automation. Global Impact.


Comments
23The reusable skills concept is what sets this apart — most browser automation tools make you re-record everything. Being able to explore a site once and save that path for agents to reuse is genuinely useful. Curious how it handles sites that change their layout frequently. Does the skill degrade gracefully or does it need a full re-record?
i write a16z speedrun scout checks within 24hours | Co-Founder & CTO at Dial AI
The real bottleneck for AI agents right now is interacting with real websites that aren't built for API access. Most agents hit walls with JavaScript-heavy sites, CAPTCHA challenges, and auth flows. BrowserAct solves this by giving agents actual browser capabilities instead of just HTTP requests. Being able to pass fingerprint checks and handle browser state properly opens up a ton of automation possibilities that were basically off-limits before. Clean structured output instead of parsing raw HTML is huge for downstream reasoning too.
It's useful for my AI agents
The remote human-handoff for CAPTCHA and 2FA is a pragmatic touch — fully autonomous agents usually just stall there. Does the handoff pause the whole workflow or can other queued sessions keep running?
i build fully functional apps & websites
the reusable skills idea is smart .. greatt work 🙌🏽
Founder @UniPath.pro · Microsoft AI-900 Certified · Building tools for students
great website it is so very useful
Founder @UniPath.pro · Microsoft AI-900 Certified · Building tools for students
great website it is so very useful
Love seeing more infrastructure being built for AI agents. The browser layer is one of the biggest bottlenecks for real-world agent workflows, and tackling sessions, verification, and reliable execution is a meaningful step forward. Congrats on the launch!
"How does it handle sites with aggressive bot detection? We build AI agent tooling and that's the wall we always hit with browser automation.
I build & lead the engineering behind AI agents · Co-Founder & VP R&D @ Dial
This is exactly the paradigm shift agents needed. The hard problem in agent development isn't reasoning - it's handling the actual web. Most browser automation tools are brittle wrappers around Selenium or Playwright, but BrowserAct's approach of giving agents a full browser layer with clean structured output is fundamentally different. The ability to handle authentication, CAPTCHAs, fingerprint protection, and multi-session isolation without state leaks opens up workflows that were basically impossible before. Particularly impressed by the reusable skills approach - being able to explore a path once and save it as reusable logic for agents is smart design.
Independent developer
This is really useful for Agnet I'll try to see if it can replace the traditional search api
Cool, it is used by all my ai agent
The MCP integration and being able to turn web workflows into reusable skills is brilliant. Makes it so much easier to move local CLI automations into the cloud without breaking.
Had this problem before with Claude before I found this page :( Will give it a try!
It's useful for my AI agents
The "clean structured output instead of raw HTML" part is the piece most browser-automation tools skip. We deal with a similar problem on the chat side (parsing messy site content into something an AI can actually answer from), so I get how much design work goes into making that step reliable. Do you handle sites that change their DOM structure between runs, or does that require a fresh pass?
I am a solo founder, I will develop my ideas to life
This is really useful for my AI agents. Smart work
23+ Years Full Stack Developer.
Nice in comparison to everything else out there for automation browsing and data extraction, but what if things change since last time an agent was running, does it still recognize the site or do you have to start from scratch?
just an ai developer
Starting from a local CLI and graduating the same workflow to cloud or MCP is a sensible adoption path — most tools force you to pick one environment up front. I'm curious how saved skills surface over MCP: does each skill become its own callable tool, or is there one generic act/extract tool that takes page state? And when several isolated sessions run in parallel, are skills shared across workspaces or scoped to each one?
This is exactly the tool I've been looking for.